


Microsoft SQL Server 2017 and Azure SQL Database - Permissions Hierarchy
Permissions hierarchy explained well for the below area
SQL Server
Source: https://docs.microsoft.com/en-us/sql/relational-databases/security/permissions-database-engine?view=sql-server-ver15
SQL Server
- Server Level Permissions
- Database Level Permissions
- Database Level Permissions - Outside the Database
Source: https://docs.microsoft.com/en-us/sql/relational-databases/security/permissions-database-engine?view=sql-server-ver15
Performing consistency check on Secondary/redundant copy of the database is fair enough?
It's
actually "NO"
Checking consistency on secondary/copy of the source database does not imply that the source/primary database is free of corruption.
Since, Source and secondary are located in different I/O subsystems involved. right? Which means - consistency checking has to be performed in all environments to examine the actual corruption (I/O Perspective).
Because, None of the SQL Server redundancy technologies propagate the data file pages and I/O subsystem corruptions. Instead - It propagates the Transaction log records to the secondaries. So, there is NO point of performing such a consistency check only in Primary or secondary.
So, performing the consistency check on all the databases in every environment is considered as mandatory!!!
Checking consistency on secondary/copy of the source database does not imply that the source/primary database is free of corruption.
Since, Source and secondary are located in different I/O subsystems involved. right? Which means - consistency checking has to be performed in all environments to examine the actual corruption (I/O Perspective).
Because, None of the SQL Server redundancy technologies propagate the data file pages and I/O subsystem corruptions. Instead - It propagates the Transaction log records to the secondaries. So, there is NO point of performing such a consistency check only in Primary or secondary.
So, performing the consistency check on all the databases in every environment is considered as mandatory!!!
SELECT COUNT(*) - Always scans all the pages/rows ?
SELECT COUNT(*) always scans every rows (all pages/rows) in the table ?
No! - Not exactly! First, Ask the question - "The table has any Index ?"
How many Index are there in that table ? Each column type/size (allocation) ?
Why should I ask these questions ?
Here is the scenario!
A table "SystemObjects" created along with 2062 records:
SELECT [schema_id], CAST([object_id] AS BIGINT) [object_id] , CAST(name AS NVARCHAR(200)) [name] INTO SystemObjects
FROM sys.system_objects
Table structure:
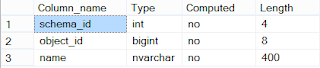
Trying to get record count (with Actual Execution Plan)
SELECT COUNT(1) FROM SystemObjects
YES! - Now, we got Table Scan operation with 94%. Yeah - This is what always happen right ?
Partially Yes and No!
Lets create a Non-Clustered Index:
CREATE NONCLUSTERED INDEX nci_obj_id ON SystemObjects([Object_id])
- Non-clustered Index has been created on Object_id column which is 8 Byte!
Trying to get record count (with Actual Execution Plan)
SELECT COUNT(1) FROM SystemObjects

We got Index Scan operation based on object_id column
Lets create an another Non-Clustered Index:
- Non-clustered Index has been created on schema_id column which is 4 Byte!
Trying to get record count again (with Actual Execution Plan)
SELECT COUNT(1) FROM SystemObjects

We got Index Scan operation again. But, this time based on schema_id column!!!
Confusing a bit right ?
See - How the Optimizer decides and goes based on what condition ? You believe Optimizer always tries to go with low cost. right ?
here is how...
Lets explore the current internal structure:
SELECT a.name, b.index_id, b.page_count, b.index_type_desc FROM sys.indexes a cross apply sys.dm_db_index_physical_stats(DB_ID(), a.[object_id] ,a.index_id,NULL,'LIMITED') AS b
WHERE a.[object_id] = OBJECT_ID('SystemObjects')

No! - Not exactly! First, Ask the question - "The table has any Index ?"
How many Index are there in that table ? Each column type/size (allocation) ?
Why should I ask these questions ?
Here is the scenario!
A table "SystemObjects" created along with 2062 records:
SELECT [schema_id], CAST([object_id] AS BIGINT) [object_id] , CAST(name AS NVARCHAR(200)) [name] INTO SystemObjects
FROM sys.system_objects
Table structure:
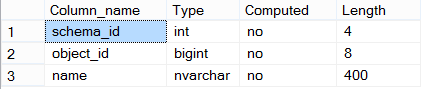
Trying to get record count (with Actual Execution Plan)
SELECT COUNT(1) FROM SystemObjects

YES! - Now, we got Table Scan operation with 94%. Yeah - This is what always happen right ?
Partially Yes and No!
Lets create a Non-Clustered Index:
CREATE NONCLUSTERED INDEX nci_obj_id ON SystemObjects([Object_id])
- Non-clustered Index has been created on Object_id column which is 8 Byte!
Trying to get record count (with Actual Execution Plan)
SELECT COUNT(1) FROM SystemObjects

We got Index Scan operation based on object_id column
Lets create an another Non-Clustered Index:
- Non-clustered Index has been created on schema_id column which is 4 Byte!
Trying to get record count again (with Actual Execution Plan)
SELECT COUNT(1) FROM SystemObjects

We got Index Scan operation again. But, this time based on schema_id column!!!
Confusing a bit right ?
See - How the Optimizer decides and goes based on what condition ? You believe Optimizer always tries to go with low cost. right ?
here is how...
Lets explore the current internal structure:
SELECT a.name, b.index_id, b.page_count, b.index_type_desc FROM sys.indexes a cross apply sys.dm_db_index_physical_stats(DB_ID(), a.[object_id] ,a.index_id,NULL,'LIMITED') AS b
WHERE a.[object_id] = OBJECT_ID('SystemObjects')

As you can see, The optimizer chooses to get the info from the smallest structure which will cost very less!!! right ? (Performance perspective)
here - The Optimizer decides to go with lowest pages to process with - So that the whole operation completes quickly/costs very less. Which is very effective/optimized operations.
The optimizer goes with "nci_schema_id" Index which is least pages (5 Pages)
If you remove the Index "nci_schema_id", The optimizer goes with "nci_obj_id" index which is least pages (6 Pages)
Once remove all the Indexes from the table - There is no other go - The Optimizer goes with Table scan (Scans all the Pages - 22 pages)
Here is the synopsis: The Optimizer goes with least pages which can be complete the process as quickly as possible with less cost!
Merry-go-round scanning ?
In SQL Server Enterprise edition, There is a strategy being followed when performing SCAN on tables!
Its also called as "Advanced Scanning"
The advanced scan feature allows multiple tasks to share full table scans. If the execution plan of a Transact-SQL statement requires a scan of the data pages in a table and the Database Engine detects that the table is already being scanned for another execution plan, the Database Engine joins the second scan to the first, at the current location of the second scan.
The Database Engine reads each page one time and passes the rows from each page to both execution plans.
This continues until the end of the table's data is reached.
At that point, the first execution plan has the complete results of a scan, but the second execution plan must still retrieve the data pages that were read before it joined the in-progress scan. The scan for the second execution plan then wraps back to the first data page of the table and scans forward to where it joined the first scan. Any number of scans can be combined like this. The Database Engine will keep looping through the data pages until it has completed all the scans. This mechanism is also called "merry-go-round scanning" and demonstrates why the order of the results returned from a SELECT statement cannot be guaranteed without an ORDER BY clause.
i.e:, assume that you have a table with 500000 pages. User-1 executes a Transact-SQL statement that requires a scan of the table. When that scan has processed 100000 pages, User-2 executes another Transact-SQL statement that scans the same table. The Database Engine schedules one set of read requests for pages after 100001, and passes the rows from each page back to both scans. When the scan reaches the 200000 th page, User-3 executes another Transact-SQL statement that scans the same table. Starting with page 200,001, the Database Engine passes the rows from each page it reads back to all three scans. After it reads the 500000 th row, the scan for User-1 is complete, and the scans for User-2 and User-3 wrap back and start to read the pages starting with page 1. When the Database Engine gets to page 100000, the scan for User-2 is completed. The scan for User-3 then keeps going alone until it reads page 200000. At this point, all the scans have been completed
Without this strategy:
"Each user would have to compete for buffer space and cause disk arm contention. The same pages would then be read once for each user, instead of read one time and shared by multiple users, slowing down performance and taxing resources"
Its also called as "Advanced Scanning"
The advanced scan feature allows multiple tasks to share full table scans. If the execution plan of a Transact-SQL statement requires a scan of the data pages in a table and the Database Engine detects that the table is already being scanned for another execution plan, the Database Engine joins the second scan to the first, at the current location of the second scan.
The Database Engine reads each page one time and passes the rows from each page to both execution plans.
This continues until the end of the table's data is reached.
At that point, the first execution plan has the complete results of a scan, but the second execution plan must still retrieve the data pages that were read before it joined the in-progress scan. The scan for the second execution plan then wraps back to the first data page of the table and scans forward to where it joined the first scan. Any number of scans can be combined like this. The Database Engine will keep looping through the data pages until it has completed all the scans. This mechanism is also called "merry-go-round scanning" and demonstrates why the order of the results returned from a SELECT statement cannot be guaranteed without an ORDER BY clause.
i.e:, assume that you have a table with 500000 pages. User-1 executes a Transact-SQL statement that requires a scan of the table. When that scan has processed 100000 pages, User-2 executes another Transact-SQL statement that scans the same table. The Database Engine schedules one set of read requests for pages after 100001, and passes the rows from each page back to both scans. When the scan reaches the 200000 th page, User-3 executes another Transact-SQL statement that scans the same table. Starting with page 200,001, the Database Engine passes the rows from each page it reads back to all three scans. After it reads the 500000 th row, the scan for User-1 is complete, and the scans for User-2 and User-3 wrap back and start to read the pages starting with page 1. When the Database Engine gets to page 100000, the scan for User-2 is completed. The scan for User-3 then keeps going alone until it reads page 200000. At this point, all the scans have been completed
Without this strategy:
"Each user would have to compete for buffer space and cause disk arm contention. The same pages would then be read once for each user, instead of read one time and shared by multiple users, slowing down performance and taxing resources"
Tempdb should be some % size of Large Database in SQL Instance ?
It doesn't seem like that!!!
There is NO any arithmetic formula to calculate Tempdb Size. Yes ?
Do we have any ?
Yes. still we can calculate/figure out by performing the following things when storing Intermediate results
1. Memory Spill - Causing by Hash Or Sort operation
2. Rebuilding Index along with SORT_IN_TEMPDB Option
3. DBCC CHECKDB on Larg Database
4. Using Temp (#/##) Table
5. Using multiple aggregations with huge data
Tempdb doesn't behave like User Databases (Say suppose, If the User database grows up to 500 GB and It'll remain same even the SQL Instance restarts. Right ?
But, The Tempdb will be recreated with the Size to whatever the size it was last set to!!!
To avoid Memory Spill:
- Omit the ORDER BY clause if you do not need the result set to be ordered.
- If ORDER BY is required, eliminate the column that participates in the multiple range scans from the ORDER BY clause.
- Using an index hint, force the optimizer to use a different access path on the table in question.
- Rewrite the query to produce a different query execution plan.
- Force serial execution of the query by adding the MAXDOP = 1 option to the end of the query or index operation
There is NO any arithmetic formula to calculate Tempdb Size. Yes ?
Do we have any ?
Yes. still we can calculate/figure out by performing the following things when storing Intermediate results
1. Memory Spill - Causing by Hash Or Sort operation
2. Rebuilding Index along with SORT_IN_TEMPDB Option
3. DBCC CHECKDB on Larg Database
4. Using Temp (#/##) Table
5. Using multiple aggregations with huge data
Tempdb doesn't behave like User Databases (Say suppose, If the User database grows up to 500 GB and It'll remain same even the SQL Instance restarts. Right ?
But, The Tempdb will be recreated with the Size to whatever the size it was last set to!!!
To avoid Memory Spill:
- Omit the ORDER BY clause if you do not need the result set to be ordered.
- If ORDER BY is required, eliminate the column that participates in the multiple range scans from the ORDER BY clause.
- Using an index hint, force the optimizer to use a different access path on the table in question.
- Rewrite the query to produce a different query execution plan.
- Force serial execution of the query by adding the MAXDOP = 1 option to the end of the query or index operation
Is always good idea to use Temporary Table ?
No. Its NOT
As far as I know, Sometimes using Temp table improves performance and Sometimes Its not!
Creating a Temp table to hold intermediate results forces SQL Server to interrupt the data pipeline through a query to persist the results to disk.
Sometimes just doing one query rather than pre-aggregating or pre-sorting can be way more efficient and lead to far lower run time and tempdb usage!
So, "Always not good using Temp table to have intermediate aggregations/processing before resulting it"
It has to be compared with various methods with/without Temp table/CTE/table variable before implementing it in production environment!
So, Its not the case always do something Or always not to do something.
Importantly, make sure to pull only the data that's really required and create Non-clustered index after the table populated when using Temp tables to gain proper statistics created on that with actual loaded data!
Also, Creating more Non-clustered Index that aren't actually being used also causes the slowness on loading data and retrieving as well!
So, Non-clustered index to be created only based on the query plan actually using.
There is no point of pulling Millions of records which is even not needed at all. Right ? But, Its happening most of times which can lead to enormous Tempdb usage!!!
As far as I know, Sometimes using Temp table improves performance and Sometimes Its not!
Creating a Temp table to hold intermediate results forces SQL Server to interrupt the data pipeline through a query to persist the results to disk.
Sometimes just doing one query rather than pre-aggregating or pre-sorting can be way more efficient and lead to far lower run time and tempdb usage!
So, "Always not good using Temp table to have intermediate aggregations/processing before resulting it"
It has to be compared with various methods with/without Temp table/CTE/table variable before implementing it in production environment!
So, Its not the case always do something Or always not to do something.
Importantly, make sure to pull only the data that's really required and create Non-clustered index after the table populated when using Temp tables to gain proper statistics created on that with actual loaded data!
Also, Creating more Non-clustered Index that aren't actually being used also causes the slowness on loading data and retrieving as well!
So, Non-clustered index to be created only based on the query plan actually using.
There is no point of pulling Millions of records which is even not needed at all. Right ? But, Its happening most of times which can lead to enormous Tempdb usage!!!
TypePerf - Command-Line Tool
We have Windows Operating system Command-Line Tool called "TypePerf" Is used to collect performance metrics periodically and store it in a File or SQL Table for further analysis on what time and what kind of overhead taken place in Server/SQL Instance like Physical/Logical Memory/Disk/Processor/IO,.. Etc,...
Here is the syntax


Here is the syntax

1. List all the Performance Objects and Counters (Without Instance)
TypePerf -q
2. List all the Performance Objects and Counters (With Instance)
TypePerf -qx
3. List counters of a specific Object (i.e: PhysicalDisk)
TypePerf -q \PhysicalDisk

4. List counters of a specific Object with Instance (i.e: PhysicalDisk)
TypePerf -qx \PhysicalDisk

5. Show metrics for a specific Object with all Instances (i.e: PhysicalDisk)
TypePerf "\PhysicalDisk(*)\Current Disk Queue Length"

* - Represents all Instance of the Object "PhysicalDisk"
6. Show metrics for a specific Object with all Instances (i.e: PhysicalDisk) only 4 samples
TypePerf "\PhysicalDisk(*)\Current Disk Queue Length" -sc 4

By Default - Shows metrics until press CTRL + C
7. Show metrics for a specific Object with all Instances (i.e: PhysicalDisk) only 4 samples for every 2 Seconds
TypePerf "\PhysicalDisk(*)\Current Disk Queue Length" -sc 4 -si 2

Ok! How to show metrics for multiple Counters\Instance ?
Lets create a Counter file contains Counters\Instances whatever you want to collect the metrics
Counter file created : C:\Personal\MyCounter.txt

Refer the Counter file

To collect the metrics in SQL Server Tables!
Create a System DSN
here is the file you have to start with - C:\windows\system32\odbcad32.exe
My System DSN Name : MySQLServer
Change the default database to: TestingDB (The database already created in my SQL Instance)

And, here is the script!

The following THREE Tables created in TestingDB Database
dbo.CounterDetails
dbo.CounterData
dbo.DisplayToID
here is the performance metrics collected in SQL Server Table in TestingDB Database

DAC - Dedicated Administrator Connection
Why It's needed ?
SQL Server grands a special connection when normal/standard connection are not possible. So, The DAC helps DBAs to query and troubleshoot problems even normal/standard connection also not responding.
Note:DAC also may not possible under extreme situation!
SQL Browser service should be running for Named Instance! But, Its not need for "Default Instance"
By default, DAC is allowed within the server. Only sysadmnin members are allowed to connect using DAC.
Connecting SQL Server from remote machine is not allowed unless they are configured "remote admin connections" using the sp_configure stored procedure
DAC only listens on the loop-back IP address (127.0.0.1), port 1434
If TCP port 1434 is not available, a TCP port is dynamically assigned when the Database Engine starts up
For DAC connection using sqlcmd
sqlcmd -SServer\Instance -A
Or
sqlcmd -S127.0.0.1 -A -- Default Instance
Or
sqlcmd -S127.0.0.1\Instance -A -- Named Instance
Or
sqlcmd -SAdmin:Server\Instance
DCA is declined with an Error 17810 If its already a DAC is running
Note: SQL Server Express does not listen on the DAC port unless started with a trace flag 7806
The DAC initially connects to the default database associated with the login. If the default database is offline or otherwise not available, the connection will return error 4060
"Microsoft recommends to connect the master database with the DAC because master is guaranteed to be available"
SQL Server prohibits running parallel queries or commands with the DAC.
The DAC session might get blocked on a latch. You might be able to terminate the DAC session using CTRL-C but it is not guaranteed. In that case, your only option may be to restart SQL Server
On cluster configurations, the DAC will be off by default
When connecting to the default instance, the DAC avoids using a SQL Server Resolution Protocol (SSRP) request to the SQL Server Browser Service when connecting
When connecting to the Azure SQL Database with the DAC, you must also specify the database name in the connection string by using the -d option.
Have you faced ?
The following Err occurred when I try to connect with SQL Server through Management studio!
Yeah!
"There was a resource limitation (insufficient memory or maximum allowed connections) on the server. (provider: Shared Memory Provider, error: 0 - No process is on the other end of the pipe.) (Microsoft SQL Server, Error: 233)"

It seems like the Maximum connection has been limited. Oh...
Then, How to fix/increase the Maximum connections ?
here we go with DAC!
Ok. I need to connect with Named Instance


Reconfiguring the running value of the User Connections option requires restarting the Database Engine!
Yeah! It worked!!!
SQL Server grands a special connection when normal/standard connection are not possible. So, The DAC helps DBAs to query and troubleshoot problems even normal/standard connection also not responding.
Note:DAC also may not possible under extreme situation!
SQL Browser service should be running for Named Instance! But, Its not need for "Default Instance"
By default, DAC is allowed within the server. Only sysadmnin members are allowed to connect using DAC.
Connecting SQL Server from remote machine is not allowed unless they are configured "remote admin connections" using the sp_configure stored procedure
DAC only listens on the loop-back IP address (127.0.0.1), port 1434
If TCP port 1434 is not available, a TCP port is dynamically assigned when the Database Engine starts up
For DAC connection using sqlcmd
sqlcmd -SServer\Instance -A
Or
sqlcmd -S127.0.0.1 -A -- Default Instance
Or
sqlcmd -S127.0.0.1\Instance -A -- Named Instance
Or
sqlcmd -SAdmin:Server\Instance
Note: SQL Server Express does not listen on the DAC port unless started with a trace flag 7806
The DAC initially connects to the default database associated with the login. If the default database is offline or otherwise not available, the connection will return error 4060
"Microsoft recommends to connect the master database with the DAC because master is guaranteed to be available"
SQL Server prohibits running parallel queries or commands with the DAC.
The DAC session might get blocked on a latch. You might be able to terminate the DAC session using CTRL-C but it is not guaranteed. In that case, your only option may be to restart SQL Server
On cluster configurations, the DAC will be off by default
When connecting to the default instance, the DAC avoids using a SQL Server Resolution Protocol (SSRP) request to the SQL Server Browser Service when connecting
When connecting to the Azure SQL Database with the DAC, you must also specify the database name in the connection string by using the -d option.
Have you faced ?
The following Err occurred when I try to connect with SQL Server through Management studio!
Yeah!
"There was a resource limitation (insufficient memory or maximum allowed connections) on the server. (provider: Shared Memory Provider, error: 0 - No process is on the other end of the pipe.) (Microsoft SQL Server, Error: 233)"

It seems like the Maximum connection has been limited. Oh...
Then, How to fix/increase the Maximum connections ?
here we go with DAC!
Ok. I need to connect with Named Instance

Check, What is the current MAX connections ?

Increase/Reset the MAX connections!

Yeah! It worked!!!
Handling JSON with SQL Server
JSON is a popular textual data format that's used for exchanging data in modern web and mobile applications.
I have a sample JSON file contains Multi-language data. How to read it from the JSON file in SQL Server ?
File Name : one.json
 here we go....
In SQL Server 2016, There is an option to consume JSON file content using : OPENJSON
DECLARE @json NVARCHAR(MAX)
SELECT @json = BulkColumn FROM OPENROWSET (BULK 'C:\Personal\one.json', SINGLE_CLOB) j
SELECT * FROM OPENJSON(@json)
WITH
(
id int 'strict $.id',
English varchar(50) '$.language.english',
Tamil nvarchar(50) '$.language.tamil',
Telugu nvarchar(50) '$.language.telugu'
)
But, The result I got was..

It says, Multi-Language data has not been parsed when read it from the file.
According to MSDN, SINGLE_CLOB - Reads the content as ASCII. But we need to read as Unicode data

So, The following option used SINGLE_NCLOB which reads the content in Unicode

DECLARE @json NVARCHAR(MAX)
SELECT @json = BulkColumn FROM OPENROWSET (BULK 'C:\Personal\one.json', SINGLE_NCLOB) j
SELECT * FROM OPENJSON(@json)
WITH
(
id int 'strict $.id',
English varchar(50) '$.language.english',
Tamil nvarchar(50) '$.language.tamil',
Telugu nvarchar(50) '$.language.telugu'
)
The result was different.... I got an Error
Msg 13609, Level 16, State 4, Line 4
JSON text is not properly formatted. Unexpected character '⁛' is found at position 0.
What next ?
Let us see, How the JSON file was saved/used the Encoding ? Yes. It was UTF-8 :)
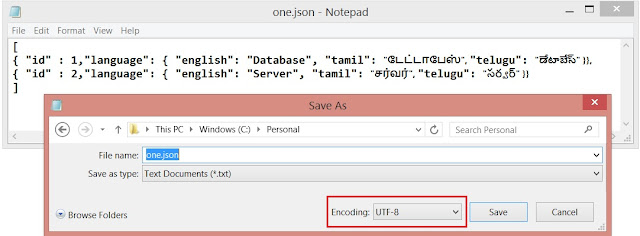

And, I tried again...
DECLARE @json NVARCHAR(MAX)
SELECT @json = BulkColumn FROM OPENROWSET (BULK 'C:\Personal\one.json', SINGLE_NCLOB) j
SELECT * FROM OPENJSON(@json)
WITH
(
id int 'strict $.id',
English varchar(50) '$.language.english',
Tamil nvarchar(50) '$.language.tamil',
Telugu nvarchar(50) '$.language.telugu'
)
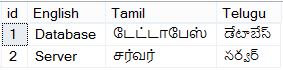
Yes. I got it now

I have a sample JSON file contains Multi-language data. How to read it from the JSON file in SQL Server ?
File Name : one.json

In SQL Server 2016, There is an option to consume JSON file content using : OPENJSON
DECLARE @json NVARCHAR(MAX)
SELECT @json = BulkColumn FROM OPENROWSET (BULK 'C:\Personal\one.json', SINGLE_CLOB) j
SELECT * FROM OPENJSON(@json)
WITH
(
id int 'strict $.id',
English varchar(50) '$.language.english',
Tamil nvarchar(50) '$.language.tamil',
Telugu nvarchar(50) '$.language.telugu'
)
But, The result I got was..

It says, Multi-Language data has not been parsed when read it from the file.
According to MSDN, SINGLE_CLOB - Reads the content as ASCII. But we need to read as Unicode data

So, The following option used SINGLE_NCLOB which reads the content in Unicode

DECLARE @json NVARCHAR(MAX)
SELECT @json = BulkColumn FROM OPENROWSET (BULK 'C:\Personal\one.json', SINGLE_NCLOB) j
SELECT * FROM OPENJSON(@json)
WITH
(
id int 'strict $.id',
English varchar(50) '$.language.english',
Tamil nvarchar(50) '$.language.tamil',
Telugu nvarchar(50) '$.language.telugu'
)
The result was different.... I got an Error
Msg 13609, Level 16, State 4, Line 4
JSON text is not properly formatted. Unexpected character '⁛' is found at position 0.
What next ?
Let us see, How the JSON file was saved/used the Encoding ? Yes. It was UTF-8 :)
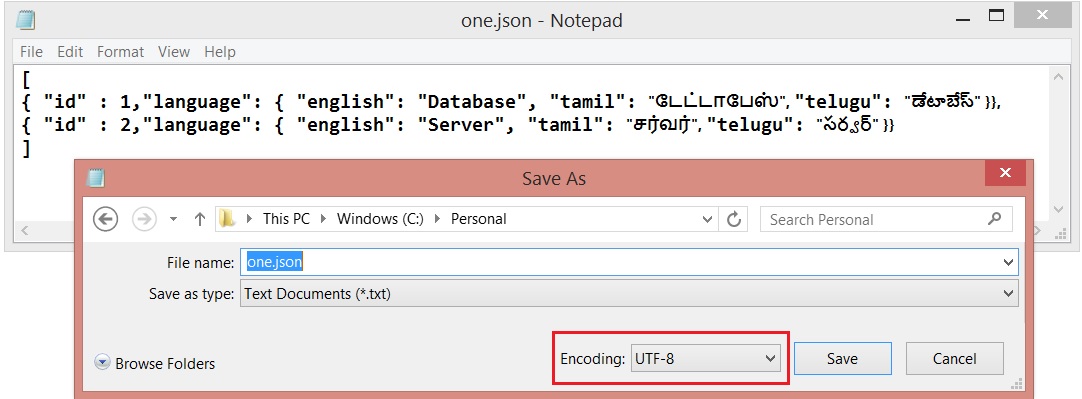
The File Encoding changed and saved it again as Unicode

And, I tried again...
DECLARE @json NVARCHAR(MAX)
SELECT @json = BulkColumn FROM OPENROWSET (BULK 'C:\Personal\one.json', SINGLE_NCLOB) j
SELECT * FROM OPENJSON(@json)
WITH
(
id int 'strict $.id',
English varchar(50) '$.language.english',
Tamil nvarchar(50) '$.language.tamil',
Telugu nvarchar(50) '$.language.telugu'
)
Yes. I got it now
Subscribe to:
Posts (Atom)